RoboVista leaderboard update: Gemini 4 Argon leads at 81.3% 🏆
The RoboVista leaderboard has been updated (2026-10-15) and now covers 30 models (23 open-weight, 7 API) on 460 multiple-choice spatial-reasoning questions over real robot scenes, each run with a standard and (for most) a chain-of-thought prompt. The benchmark is available on Hugging Face.
Gemini 4 Argon is the new top model at 81.3%, ahead of GPT-6 Astra and Claude Fable 5.1, at the lowest evaluation cost of the three. Compared with Gemini 3 Flash, it improves in every robotics domain. (Announcement on X)
| Model | Weights | Standard | CoT | Scene | Planning |
|---|---|---|---|---|---|
| gemini-4-argon | API | 81.3 | 81.3 | 80.7 | 81.8 |
| gpt-6-astra | API | 75.0 | 73.9 | 74.5 | 75.7 |
| gemini-3-flash-preview | API | 68.9 | 65.4 | 69.9 | 67.6 |
| claude-fable-5.1 | API | 63.9 | — | 65.0 | 60.8 |
| qwen3.5-397b-a17b | open | 55.2 | 52.8 | 58.2 | 48.6 |
| gpt-5-0 | API | 54.6 | 54.6 | 56.2 | 51.4 |
| qwen3.6-27b | open | 53.5 | 54.4 | 55.9 | 48.0 |
| gemma4-31b | open | 51.5 | 55.4 | 54.9 | 43.9 |
Top 8 by standard-prompt accuracy (%). The best open-weight model is qwen3.5-397b-a17b at 55.2%. See the full leaderboard for all 30 models and the per-domain breakdown.
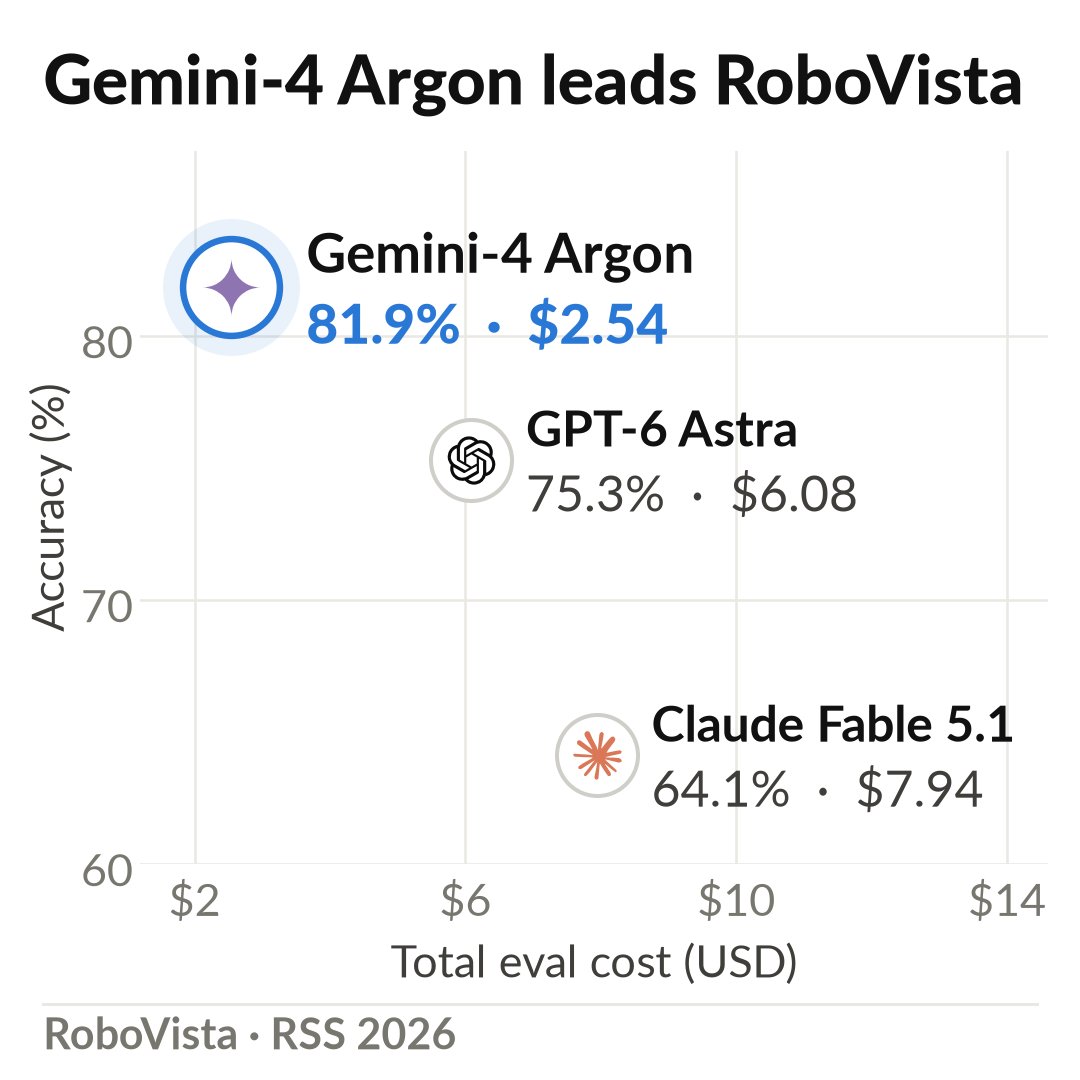
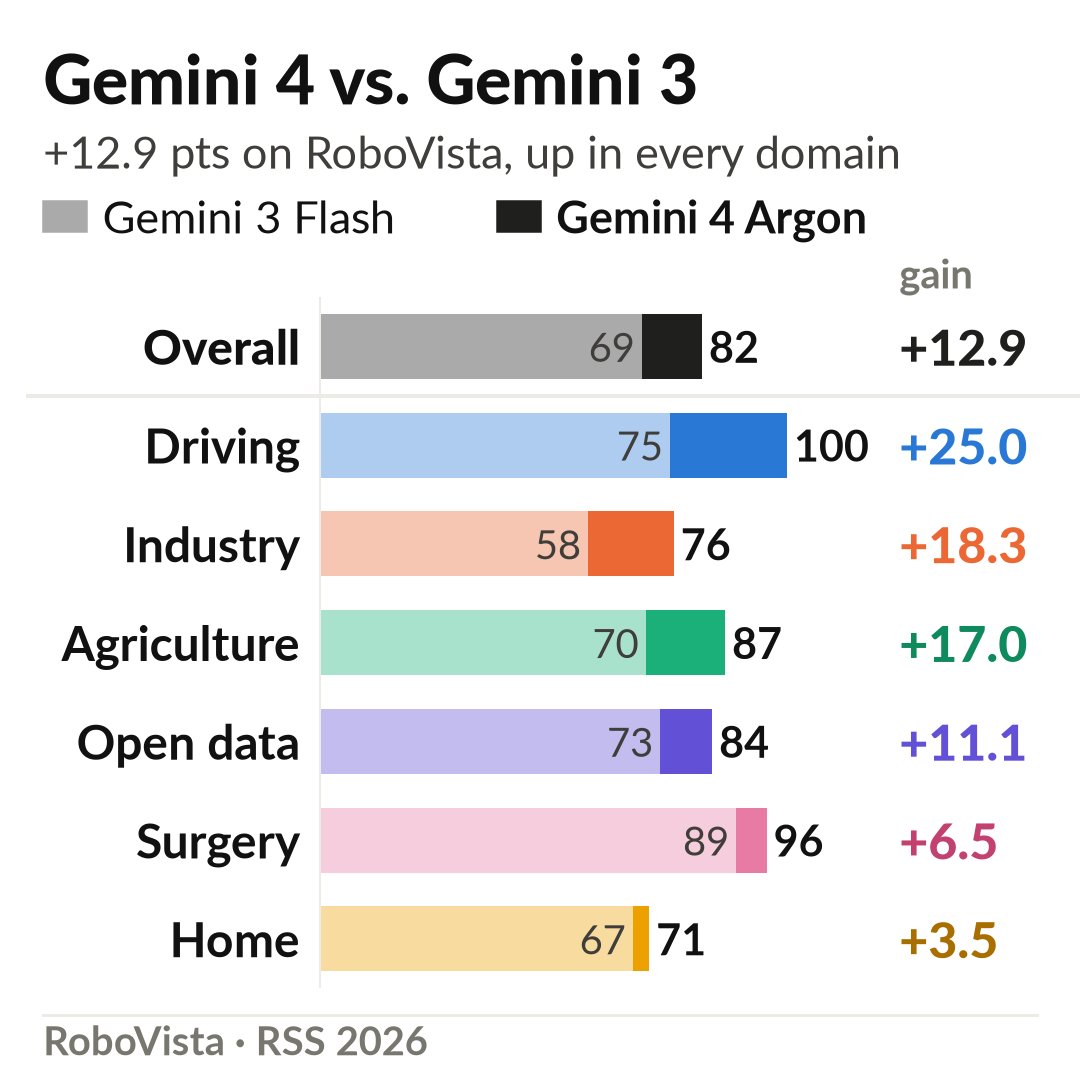
Charts from the announcement on X. They were made before the leaderboard's answer re-parsing, so their scores are a few tenths of a point higher (e.g. 81.9% vs. 81.3% for Gemini 4 Argon).